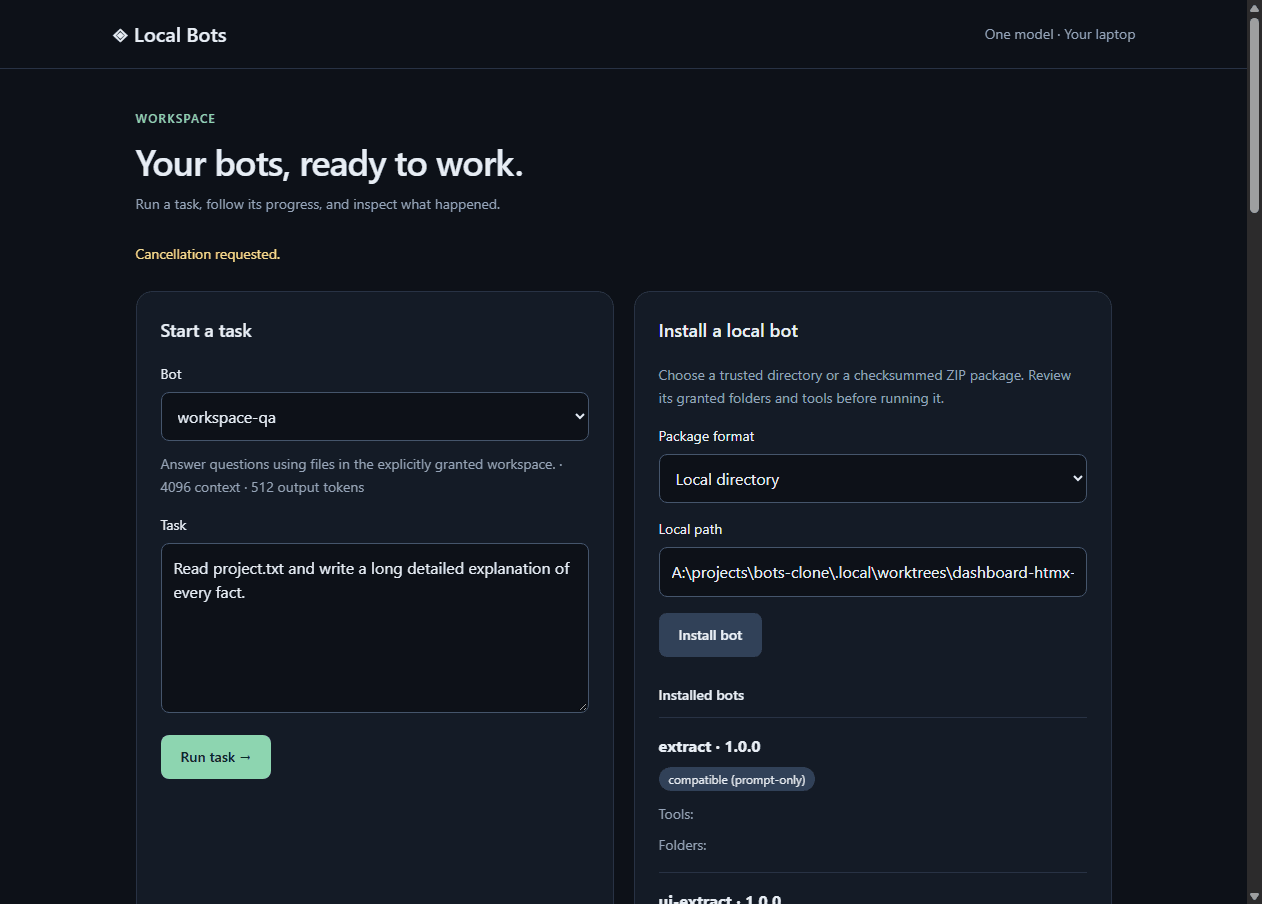
Running multiple specialist roles within one laptop’s model and memory budget.
Shared one Qwen3-1.7B model served by llama.cpp, serialized model acquisition, and bounded queued work. Bots specialize through configuration and optional adapters rather than separate resident model copies.